
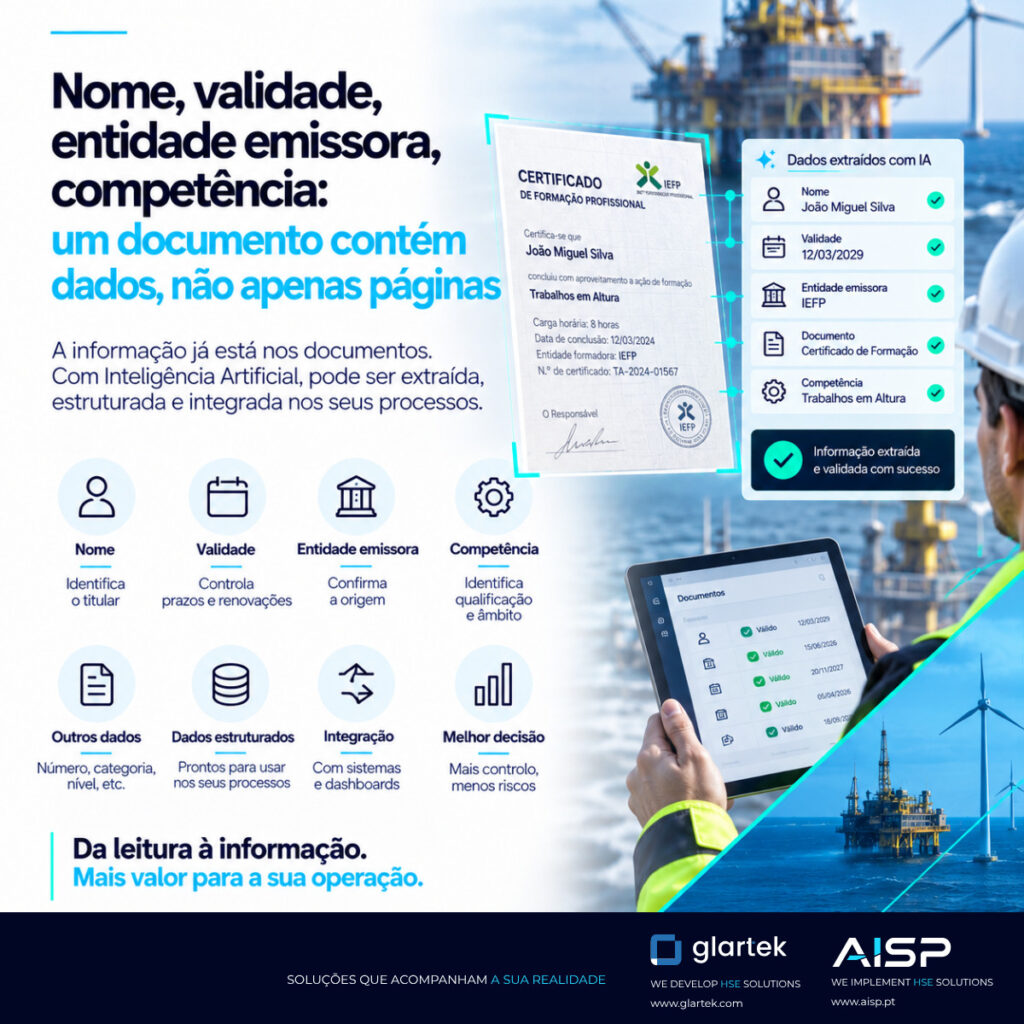
A digital document is not just a set of pages stored on a platform. Document data also has value.
Inside a certificate, report, declaration, insurance policy, technical sheet or record, there is information that the organisation can identify, structure and use in other processes.
Names, dates, issuing bodies, competences, certificate numbers, references, results or deadlines are examples of data that many organisations still look up manually whenever they need it.
That is why the evolution of document management is precisely about changing this logic.
Instead of treating the document only as a file, you can also treat it as a source of data.
The document already contains the information
For example, consider a training certificate.
Visually, we have a document.
From a process point of view, however, we may have different pieces of information:
- worker’s name;
- identification number;
- training completed;
- competence acquired;
- training provider;
- issue date;
- expiry date;
- duration;
- certificate reference.
In fact, each of these items may be relevant to a different decision.
For example, the expiry date can feed an alert.
In addition, you can link the competence to a role.
The issuing body can form part of the validation rules.
Finally, you can compare the holder with the worker linked to the document.
The information already existed. However, the problem was that it stayed only on the page.
When a PDF still requires manual work
Digitising processes does not simply mean replacing paper with PDF.
If, after uploading a document to a platform, someone still has to open it, find the relevant fields and enter the same data manually, an important part of the process still works as before.
This becomes particularly relevant when there are hundreds or thousands of documents.
As a result, small tasks repeated many times turn into significant hours of administrative work.
In addition, the chances of transcription, classification or matching errors increase.
Turning document content into structured data
OCR and artificial intelligence technologies can help identify information that already exists in documents.
However, the goal is not simply to reproduce all the text.
In fact, it is to identify the fields that matter to the process.
For example, on a certificate the training may be what matters.
On an insurance policy, the insurer, the policy number and the expiry date may matter.
On an equipment certificate, the serial number, inspection and next review date may be relevant.
A medical fitness certificate may contain items that help determine whether the evidence provided meets the applicable requirement.
Thus, the structure always depends on the type of document and the process the organisation wants to control.
Document data can feed validations
Once data no longer stays trapped inside documents, the platform’s rules can use it.
For example, extracting the expiry date makes it possible to check automatically whether the document is still within the defined period.
Likewise, the system can compare the holder’s identity with the linked worker.
Similarly, it can check a competence against the requirements of a given role.
It can also assess the issuing body against criteria defined in advance.
As a result, the review no longer depends solely on reading the file.
From document data to competence matrices
This approach is particularly relevant in organisations that need to control competences.
For example, imagine a company with hundreds of workers and different roles.
Instead of keeping the information only inside certificates, extracted data can help build a view of:
- who holds a given competence;
- when they acquired it;
- how long it remains valid;
- what documentary evidence supports it;
- which roles require it;
- who needs a renewal.
However, the document still serves as evidence.
But the information also starts to feed operational management.
Alerts based on document data
In addition, validity is another example.
As long as the date exists only inside a PDF, someone will have to look it up or record it manually.
Once structured, it can automatically generate:
- expiry alerts;
- lists of documents to renew;
- notifications;
- indicators;
- task prioritisation.
The document is therefore no longer passive.
Instead, the information it contains starts to trigger processes.
Dashboards without opening files
Moreover, the same logic applies to indicators.
A platform with structured data can show information such as:
- valid documents;
- expired documents;
- workers by competence;
- suppliers with pending documentation;
- certifications to renew;
- unmet requirements;
- compliance levels by project.
In this way, teams no longer need to open each file to answer basic operational questions.
Extracted document data needs context
However, extracting information does not automatically mean interpreting it correctly.
A date found in a document may be an issue, expiry, inspection or review date.
A competence may appear because the worker holds it or simply because a text mentions it.
Likewise, an entity may be the issuing body, the client or another organisation the document cites.
Therefore, a robust solution needs to combine:
extraction + structure + rules + context.
In fact, it is this combination that turns text into usable information.
AI as support, not as an absence of control
Artificial intelligence can significantly speed up document reading and structuring.
But there must be mechanisms to deal with uncertainty.
When the system cannot identify a field reliably, finds contradictory information or lacks sufficient evidence, the process must allow the document to go to human review.
Automation adds value when it reduces repetitive work and preserves the rigour of decisions.
The document starts to feed the process
We can sum up the big change simply.
In a traditional model:
Document → human consultation
In a more advanced model:
Document → data → validation → process → decision
However, the file is still important.
But it is no longer the end point.
Instead, it becomes a source of information for different parts of the organisation.
From pages to operational information
This is precisely where the potential of the new generation of document management lies.
The documents organisations already receive contain much of the information their processes need.
The question, therefore, is how to use it.
Extracting and structuring this data reduces manual data entry, improves traceability, speeds up validations and creates more useful indicators for operations.
Because a document does not contain only pages.
It contains data that can feed decisions.
Read also: Automation in document management and Artificial intelligence and machine learning for detecting anomalous patterns.
To learn about the rules on processing personal data in documents, see the Portuguese Data Protection Authority (CNPD).